Version B evidence
Experiment dashboard
Every value is read from artifacts/results at request time, never hardcoded.
How to read these metrics
- F1
- Balance of precision and recall. The headline detection metric on the test split.
- AUROC
- Probability that a random positive case scores above a random negative one.
- PR-AUC
- Precision-recall area. More informative than AUROC when classes are imbalanced.
- MCC
- Matthews correlation coefficient. A balanced single-number quality score.
- ECE
- Expected calibration error. Gap between predicted probabilities and observed frequencies.
- Brier
- Mean squared error of the predicted probabilities. Lower is better.
- Platt / isotonic
- Post-hoc calibration methods. Platt is the deployable default here.
- SHAP
- Per-feature attribution explaining how the model reached a score.
- McNemar
- Paired significance test between two classifiers on the same test cases.
- Bootstrap CI
- Confidence interval from resampling with replacement.
EC-XGB under domain shift (B6) — deployed model
m3 variant (Evidence-Consistent XGBoost), seeds 42/123/456, threshold 0.5. Standard = B2 XGBoost trained on HaluEval only; EC-XGB adds the RAGTruth non-QA training rows. Flagged = share above 0.5.
| Corpus | Model | Rows | F1 | AUROC | Flagged | ECE |
|---|---|---|---|---|---|---|
| RAGTruth (all test tasks) | Standard XGBoost | 2700 | 0.5181 | 0.4753 | 99.9% | 0.6346 |
| RAGTruth (all test tasks) | m3 EC-XGB (deployed) | 2700 | 0.5608 | 0.5815 | 61.3% | 0.2782 |
| RAGTruth QA test (held out) | Standard XGBoost | 900 | 0.3022 | 0.5465 | 99.9% | 0.8149 |
| RAGTruth QA test (held out) | m3 EC-XGB (deployed) | 900 | 0.3081 | 0.5491 | 97.4% | 0.7433 |
| FaithBench | Standard XGBoost | 750 | 0.8130 | 0.5089 | 99.5% | 0.2917 |
| FaithBench | m3 EC-XGB (deployed) | 750 | 0.1201 | 0.5941 | 7.3% | 0.4500 |
EC-XGB ablation, operating point, and display calibration (B6)
b6_model_comparison.csv · b6_strict_mode.json · b6_calibration.json
| Variant | Features | F1 | AUROC | MCC | ECE |
|---|---|---|---|---|---|
| Standard XGBoost | 26 | 0.9844 | 0.9980 | 0.9693 | 0.0066 |
| m1 debias + constraints | 26 | 0.9852 | 0.9976 | 0.9708 | 0.0051 |
| m2 + claim features | 34 | 0.9857 | 0.9984 | 0.9717 | 0.0078 |
| m3 EC-XGB (deployed) | 35 | 0.9855 | 0.9984 | 0.9715 | 0.0074 |
Operating point at a 5.0% false-positive budget: test FPR 4.2%–5.1% with recall 99.0%–99.5%.
Deployed display score (platt on 5,034 RAGTruth QA calibration rows): held-out ECE 0.726 → 0.126.
Zero-shot transfer — B2 XGBoost on external RAGTruth + FaithBench (B3)
No training on external data; threshold fixed at 0.5; source-group bootstrap CIs (1,000 resamples).
| Subset | Rows | Groups | F1 | AUROC | ECE | Pred. pos | Label pos |
|---|---|---|---|---|---|---|---|
| RAGTruth QA test | 900 | 150 | 0.3022 | 0.5398 | 0.8185 | 99.9% | 17.8% |
| RAGTruth (all tasks) | 17790 | 2965 | 0.6031 | 0.4965 | 0.5601 | 99.8% | 43.1% |
| RAGTruth train (covariate) | 15090 | 2515 | 0.6173 | 0.5012 | 0.5454 | 99.8% | 44.5% |
| FaithBench | 750 | 750 | 0.8130 | 0.5314 | 0.3009 | 99.5% | 68.1% |
| ragtruth_task_qa | 5934 | 989 | 0.4515 | 0.5868 | 0.7039 | 99.6% | 29.1% |
| ragtruth_task_summarization | 5658 | 943 | 0.4603 | 0.6317 | 0.6880 | 99.7% | 29.8% |
| ragtruth_task_data_to_text | 6198 | 1033 | 0.8140 | 0.5777 | 0.3057 | 100.0% | 68.6% |
In-domain reference (B2 test): F1 0.9846 · AUROC 0.9979 — the transfer gap below is the core robustness finding.
Transfer comparison (Δ vs in-domain)
b3_transfer_comparison.csv
| Subset | Rows | F1 | AUROC | ΔF1 | ΔAUROC |
|---|---|---|---|---|---|
| RAGTruth QA test | 900 | 0.3022 | 0.5398 | -0.6825 | -0.4581 |
| RAGTruth (all tasks) | 17790 | 0.6031 | 0.4965 | -0.3815 | -0.5014 |
| RAGTruth train (covariate) | 15090 | 0.6173 | 0.5012 | -0.3673 | -0.4967 |
| FaithBench | 750 | 0.8130 | 0.5314 | -0.1716 | -0.4665 |
| ragtruth_task_qa | 5934 | 0.4515 | 0.5868 | -0.5331 | -0.4111 |
| ragtruth_task_summarization | 5658 | 0.4603 | 0.6317 | -0.5244 | -0.3662 |
| ragtruth_task_data_to_text | 6198 | 0.8140 | 0.5777 | -0.1706 | -0.4203 |
Subgroup metrics (rows ≥ 100, groups ≥ 20)
b3_subgroup_metrics.csv — reported only above minimums.
| Dimension | Subgroup | Rows | F1 | ECE | Note |
|---|---|---|---|---|---|
| task | data_to_text | 6198 | 0.8140 | 0.3064 | |
| task | qa | 5934 | 0.4515 | 0.7037 | |
| task | summarization | 5658 | 0.4603 | 0.6882 | |
| official_split | test | 2700 | 0.5181 | 0.6424 | |
| official_split | train | 15090 | 0.6173 | 0.5457 | |
| domain | cnn_dm | 3768 | 0.4738 | 0.6766 | |
| domain | marco | 5934 | 0.4515 | 0.7037 | |
| domain | recent_news | 1890 | 0.4327 | 0.7114 | |
| domain | yelp | 6198 | 0.8140 | 0.3064 | |
| generator_model | gpt-3.5-turbo-0613 | 2965 | 0.2390 | 0.8528 | |
| generator_model | gpt-4-0613 | 2965 | 0.2426 | 0.8470 | |
| generator_model | llama-2-13b-chat | 2965 | 0.7225 | 0.4286 | |
| generator_model | llama-2-70b-chat | 2965 | 0.6399 | 0.5233 | |
| generator_model | llama-2-7b-chat | 2965 | 0.7638 | 0.3768 | |
| generator_model | mistral-7B-instruct | 2965 | 0.7950 | 0.3337 | |
| quality | good | 17617 | 0.6060 | 0.5574 | |
| quality | incorrect_refusal | 144 | 0.0139 | 0.9835 | |
| quality | truncated | 29 | — | — | |
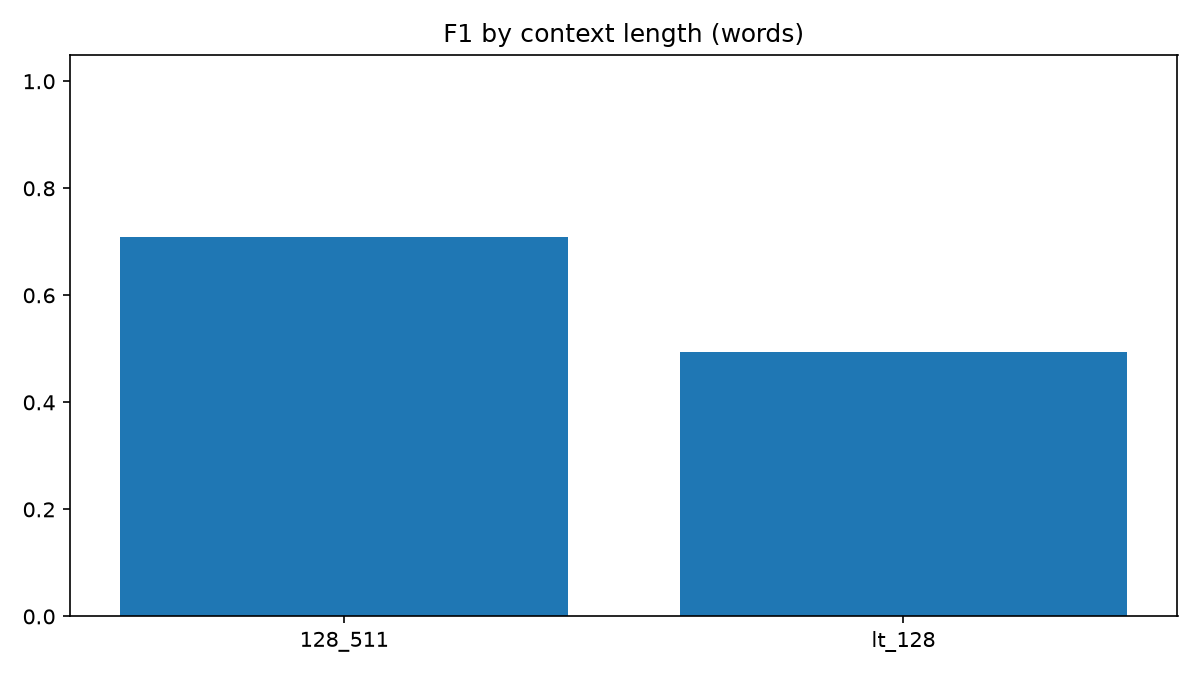
| context_length | 128_511 | 8326 | 0.7091 | 0.4437 | |
| context_length | 512_1023 | 1 | — | — | |
| context_length | lt_128 | 9463 | 0.4940 | 0.6629 | |
| answer_length | 32_127 | 9004 | 0.5091 | 0.6497 | |
| answer_length | ge_128 | 8327 | 0.7091 | 0.4438 | |
| answer_length | lt_32 | 459 | 0.1201 | 0.9219 | |
| label_type | Evident Conflict | 3713 | — | — | |
| label_type | Evident Baseless Info | 4393 | — | — | |
| label_type | Subtle Conflict | 184 | — | — | |
| label_type | Subtle Baseless Info | 1872 | — | — | |
| label_type | no_span | 10126 | — | — | |
| generator_model | Anthropic/claude-3-5-sonnet-20240620 | 75 | — | — | |
| generator_model | Qwen/Qwen2.5-7B-Instruct | 75 | — | — | |
| generator_model | cohere/command-r-08-2024 | 75 | — | — | |
| generator_model | google/gemini-1.5-flash-001 | 75 | — | — | |
| generator_model | meta-llama/Meta-Llama-3.1-70B-Instruct | 75 | — | — | |
| generator_model | meta-llama/Meta-Llama-3.1-8B-Instruct | 75 | — | — | |
| generator_model | microsoft/Phi-3-mini-4k-instruct | 75 | — | — | |
| generator_model | mistralai/Mistral-7B-Instruct-v0.3 | 75 | — | — | |
| generator_model | openai/GPT-3.5-Turbo | 75 | — | — | |
| generator_model | openai/gpt-4o | 75 | — | — |
Context-length robustness (figure)
F1 by context length (words), RAGTruth.
Bootstrap CIs + label sensitivity
Source-group resampling, seed 777 (B3).
- RAGTruth QA testF1 [0.260, 0.342] · AUROC [0.514, 0.607]
- RAGTruth (all tasks)F1 [0.593, 0.612] · AUROC [0.489, 0.511]
- RAGTruth train (covariate)F1 [0.608, 0.627] · AUROC [0.493, 0.517]
- FaithBenchF1 [0.788, 0.835] · AUROC [0.511, 0.601]
- ragtruth_task_qaF1 [0.435, 0.468] · AUROC [0.598, 0.631]
- ragtruth_task_summarizationF1 [0.447, 0.475] · AUROC [0.616, 0.646]
- ragtruth_task_data_to_textF1 [0.807, 0.821] · AUROC [0.573, 0.602]
FaithBench label-mapping sensitivity
The measured F1 depends on which FaithBench labels count as positive.
| Mapping | Pos. | Neg. | F1 | AUROC | MCC |
|---|---|---|---|---|---|
| Primary (worst + question + unwanted) | 511 | 239 | 0.8130 | 0.5568 | 0.1071 |
| Majority (question + unwanted) | 465 | 285 | 0.7680 | 0.5402 | 0.0935 |
| Strict (unwanted only) | 439 | 311 | 0.7409 | 0.5524 | 0.0870 |