Version B evidence
Experiment dashboard
Every value is read from artifacts/results at request time, never hardcoded.
How to read these metrics
- F1
- Balance of precision and recall. The headline detection metric on the test split.
- AUROC
- Probability that a random positive case scores above a random negative one.
- PR-AUC
- Precision-recall area. More informative than AUROC when classes are imbalanced.
- MCC
- Matthews correlation coefficient. A balanced single-number quality score.
- ECE
- Expected calibration error. Gap between predicted probabilities and observed frequencies.
- Brier
- Mean squared error of the predicted probabilities. Lower is better.
- Platt / isotonic
- Post-hoc calibration methods. Platt is the deployable default here.
- SHAP
- Per-feature attribution explaining how the model reached a score.
- McNemar
- Paired significance test between two classifiers on the same test cases.
- Bootstrap CI
- Confidence interval from resampling with replacement.
Calibration under distribution shift (B4)
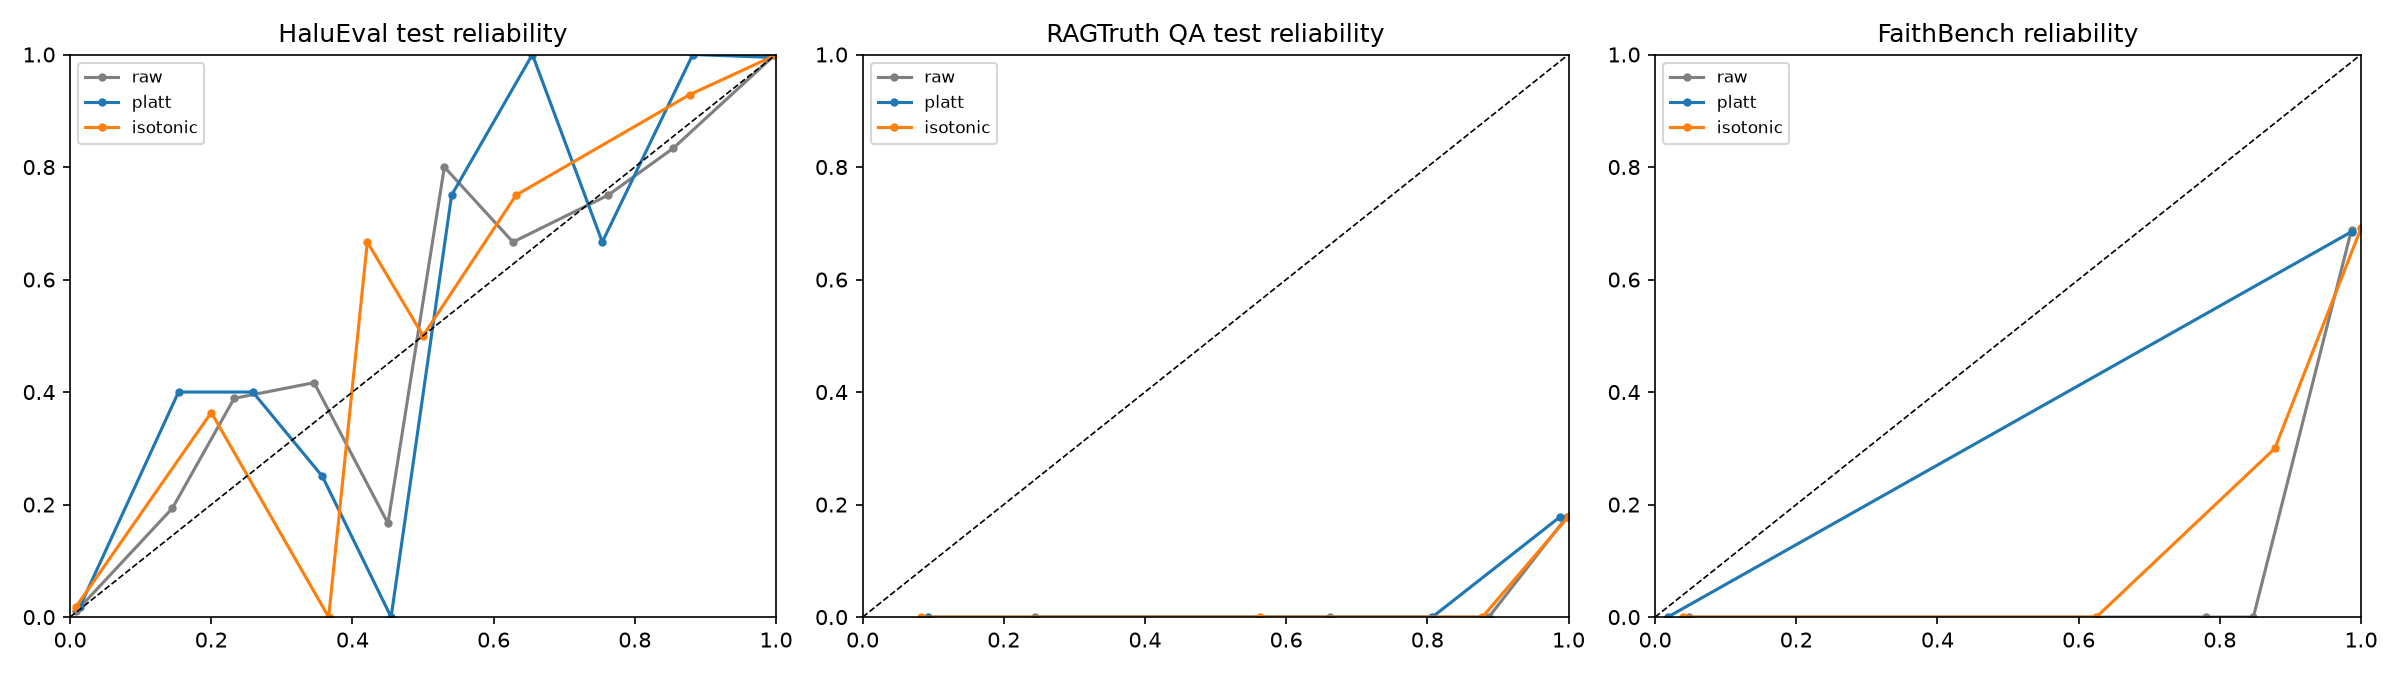
Source calibrators fit on HaluEval validation only (seeds 42/123/456); applied unchanged to external sets.
Predeclared deployable calibrator: Platt (isotonic reported for comparison, roadmap B4.2).
Full metric table — ECE / ACE / Brier / NLL per subset × method
| Subset | Method | ECE | ACE | Brier | NLL | Slope | F1 | AUROC |
|---|---|---|---|---|---|---|---|---|
| HaluEval test (in-domain) | raw | 0.0045 | 0.0036 | 0.0117 | 0.0449 | 1.0746 | 0.9846 | 0.9979 |
| HaluEval test (in-domain) | platt | 0.0091 | 0.0134 | 0.0129 | 0.0579 | 1.1585 | 0.9848 | 0.9979 |
| HaluEval test (in-domain) | isotonic | 0.0070 | 0.0078 | 0.0124 | 0.0727 | 0.8536 | 0.9844 | 0.9972 |
| RAGTruth QA test | raw | 0.8185 | 0.8185 | 0.8164 | 5.1976 | 0.1386 | 0.3022 | 0.5398 |
| RAGTruth QA test | platt | 0.8089 | 0.8089 | 0.8011 | 3.6232 | 0.5499 | 0.3022 | 0.5398 |
| RAGTruth QA test | isotonic | 0.8204 | 0.8204 | 0.8200 | 29.5064 | 0.2418 | 0.3023 | 0.5023 |
| RAGTruth summarization | raw | 0.6880 | 0.6880 | 0.6825 | 3.2879 | 0.9687 | 0.4603 | 0.6317 |
| RAGTruth summarization | platt | 0.6858 | 0.6858 | 0.6804 | 3.0311 | 6.5662 | 0.4603 | 0.6317 |
| RAGTruth summarization | isotonic | 0.6977 | 0.6977 | 0.6968 | 24.9148 | 0.2517 | 0.4603 | 0.5074 |
| RAGTruth data-to-text | raw | 0.3057 | 0.3057 | 0.3084 | 1.5489 | 0.7136 | 0.8140 | 0.5777 |
| RAGTruth data-to-text | platt | 0.3009 | 0.3009 | 0.3058 | 1.3767 | 4.8861 | 0.8140 | 0.5777 |
| RAGTruth data-to-text | isotonic | 0.3136 | 0.3136 | 0.3136 | 11.3051 | 0.0564 | 0.8140 | — |
| RAGTruth (all) | raw | 0.5601 | 0.5601 | 0.5586 | 3.0661 | -0.0448 | 0.6031 | 0.4965 |
| RAGTruth (all) | platt | 0.5544 | 0.5544 | 0.5526 | 2.4832 | 1.6520 | 0.6031 | 0.4965 |
| RAGTruth (all) | isotonic | 0.5666 | 0.5666 | 0.5661 | 20.3179 | 0.3520 | 0.6031 | 0.5049 |
| FaithBench | raw | 0.3009 | 0.3009 | 0.3049 | 1.4339 | 0.3575 | 0.8130 | 0.5314 |
| FaithBench | platt | 0.3002 | 0.3002 | 0.3050 | 1.3610 | 1.0344 | 0.8130 | 0.5314 |
| FaithBench | isotonic | 0.3123 | 0.3123 | 0.3118 | 11.0824 | 0.2263 | 0.8130 | 0.5162 |
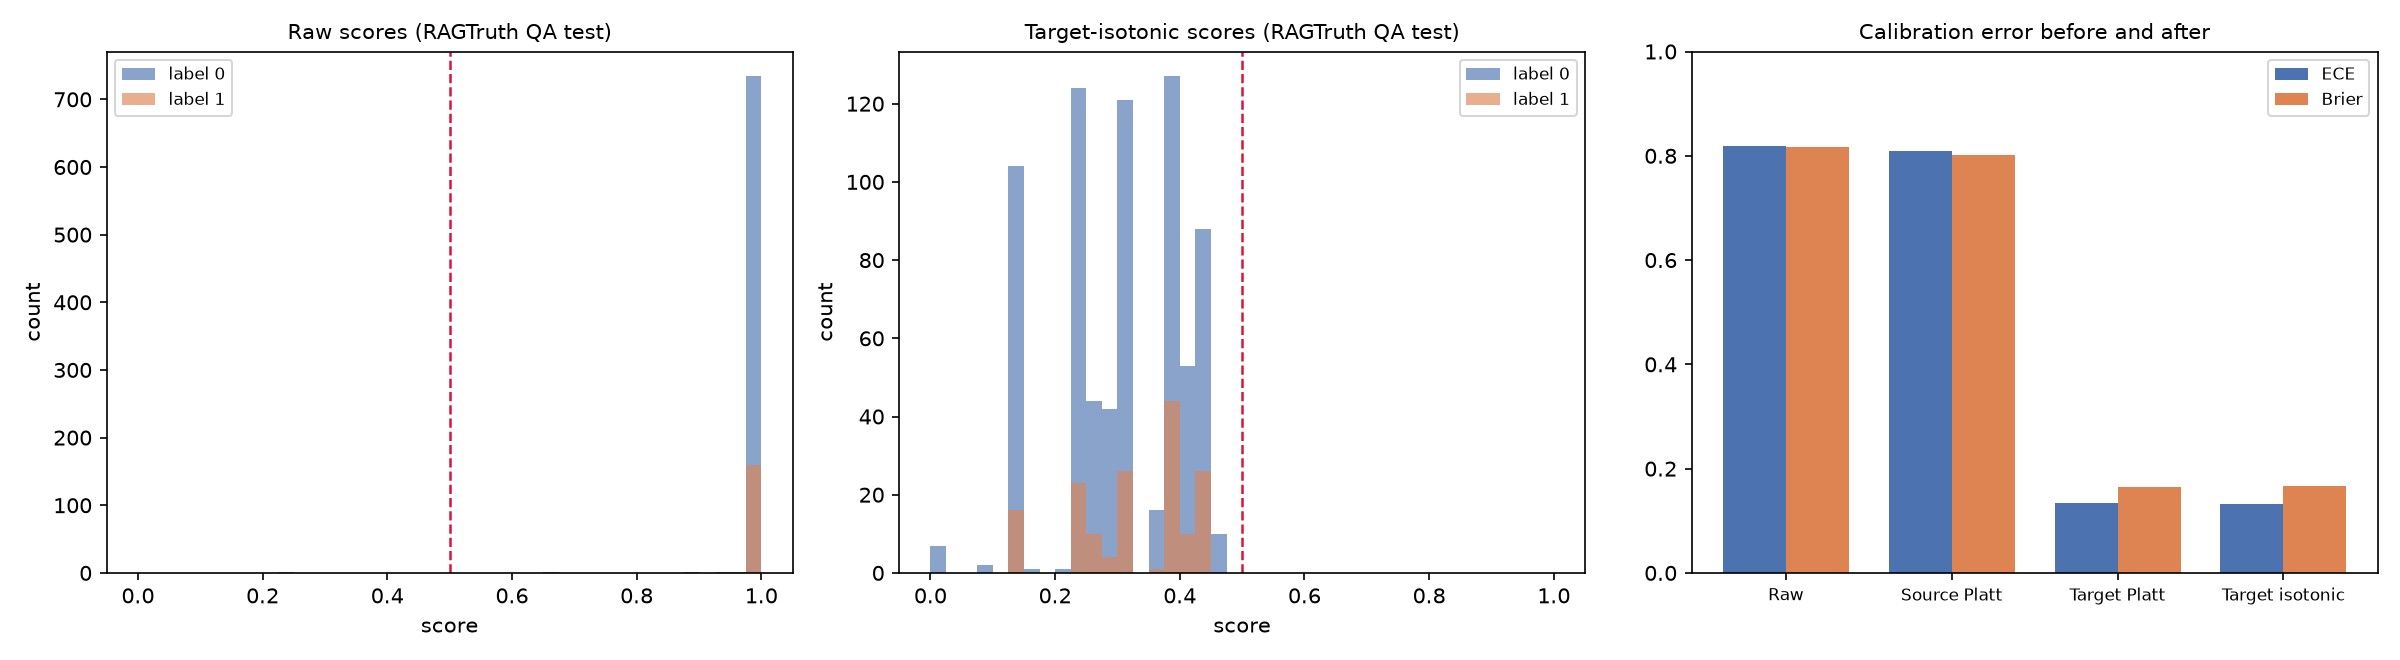
Target calibration — RAGTruth QA train → test
Disjoint source groups; the headline shift fix.
5,034 calibration rows · 900 test rows · 0 overlapping groups removed.
| Configuration | ECE | Brier | NLL |
|---|---|---|---|
| Raw source scores | 0.8185 | 0.8164 | 5.1976 |
| Source-calibrated (Platt) | 0.8089 | 0.8011 | 3.6232 |
| Source-calibrated (isotonic) | 0.8204 | 0.8200 | 29.5064 |
| Target-calibrated (Platt) | 0.1335 | 0.1639 | 0.5137 |
| Target-calibrated (isotonic) | 0.1316 | 0.1663 | 0.5279 |
Source calibration does not transfer (ECE ≈ 0.81 on QA test); fitting on target data restores calibration (ECE ≈ 0.13).
Reliability diagrams (figure)
Calibration shift (figure)
Subgroup calibration (rows ≥ 100, groups ≥ 20)
b4_subgroup_calibration.csv — pooled fallback below minimums.
| Dimension | Subgroup | Rows | Raw ECE | Platt ECE | Isotonic ECE | Note |
|---|---|---|---|---|---|---|
| task | data_to_text | 6198 | 0.3064 | 0.3012 | 0.3136 | |
| task | qa | 5934 | 0.7037 | 0.6940 | 0.7055 | |
| task | summarization | 5658 | 0.6882 | 0.6858 | 0.6970 | |
| official_split | test | 2700 | 0.6424 | 0.6370 | 0.6484 | |
| official_split | train | 15090 | 0.5457 | 0.5398 | 0.5516 | |
| domain | cnn_dm | 3768 | 0.6766 | 0.6739 | 0.6850 | |
| domain | marco | 5934 | 0.7037 | 0.6940 | 0.7055 | |
| domain | recent_news | 1890 | 0.7114 | 0.7094 | 0.7211 | |
| domain | yelp | 6198 | 0.3064 | 0.3012 | 0.3136 | |
| generator_model | gpt-3.5-turbo-0613 | 2965 | 0.8528 | 0.8483 | 0.8597 | |
| generator_model | gpt-4-0613 | 2965 | 0.8470 | 0.8425 | 0.8527 | |
| generator_model | llama-2-13b-chat | 2965 | 0.4286 | 0.4221 | 0.4344 | |
| generator_model | llama-2-70b-chat | 2965 | 0.5233 | 0.5171 | 0.5292 | |
| generator_model | llama-2-7b-chat | 2965 | 0.3768 | 0.3699 | 0.3821 | |
| generator_model | mistral-7B-instruct | 2965 | 0.3337 | 0.3274 | 0.3395 | |
| quality | good | 17617 | 0.5574 | 0.5516 | 0.5634 | |
| quality | incorrect_refusal | 144 | 0.9835 | 0.9743 | 0.9862 | |
| quality | truncated | 29 | — | — | — | |
| context_length | 128_511 | 14526 | 0.5580 | 0.5519 | 0.5637 | |
| context_length | 512_1023 | 2460 | 0.5548 | 0.5508 | 0.5624 | |
| context_length | ge_1024 | 552 | 0.5962 | 0.5924 | 0.6032 | |
| context_length | lt_128 | 252 | 0.6715 | 0.6626 | 0.6741 | |
| answer_length | 32_127 | 9004 | 0.6497 | 0.6440 | 0.6555 | |
| answer_length | ge_128 | 8327 | 0.4438 | 0.4380 | 0.4501 | |
| answer_length | lt_32 | 459 | 0.9219 | 0.9136 | 0.9240 | |
| generator_model | Anthropic/claude-3-5-sonnet-20240620 | 75 | — | — | — | |
| generator_model | Qwen/Qwen2.5-7B-Instruct | 75 | — | — | — | |
| generator_model | cohere/command-r-08-2024 | 75 | — | — | — | |
| generator_model | google/gemini-1.5-flash-001 | 75 | — | — | — | |
| generator_model | meta-llama/Meta-Llama-3.1-70B-Instruct | 75 | — | — | — | |
| generator_model | meta-llama/Meta-Llama-3.1-8B-Instruct | 75 | — | — | — | |
| generator_model | microsoft/Phi-3-mini-4k-instruct | 75 | — | — | — | |
| generator_model | mistralai/Mistral-7B-Instruct-v0.3 | 75 | — | — | — | |
| generator_model | openai/GPT-3.5-Turbo | 75 | — | — | — | |
| generator_model | openai/gpt-4o | 75 | — | — | — |